Deep Dive · Oct 16, 2026 · 7 min read
Reducing LLM Hallucinations: Engineering Techniques That Work
Grounding, constrained output, verification, and abstention: a toolkit with code for making outputs dependable.
 Short version← Why AI Makes Things Up, and How to Reduce It
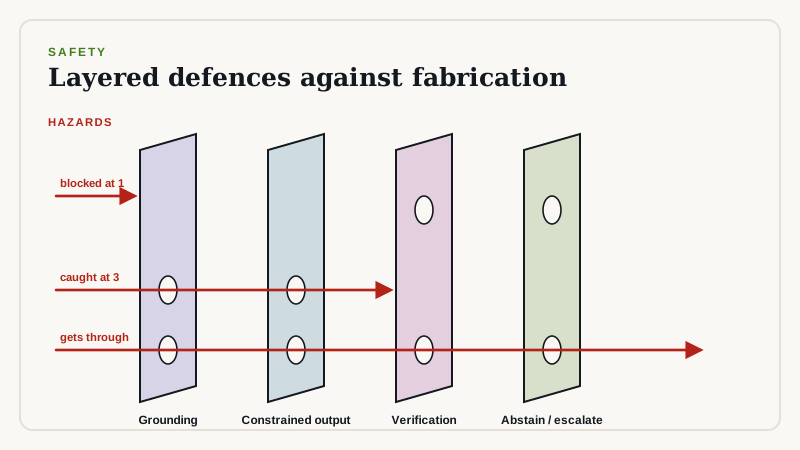
Models generate plausible text, whether or not it is true. You cannot eliminate hallucinations, but you can engineer a system where they are rare and caught.
1. Ground the answer
Supply the facts in the prompt via retrieval and instruct the model to use only those. Include source ids so claims can be traced.
2. Constrain the output
Where the output has structure, enforce it. Use JSON schemas, enumerations, and ranges so the model cannot invent a field value outside the allowed set.
{
  "type": "object",
  "properties": {
    "category": {"type": "string", "enum": ["billing", "shipping", "technical", "other"]},
    "answer": {"type": "string"},
    "source_ids": {"type": "array", "items": {"type": "integer"}, "minItems": 1}
  },
  "required": ["category", "answer", "source_ids"],
  "additionalProperties": false
}
3. Verify claims after generation
Check that cited sources exist, quotes appear in them, and numbers match source data. For high-stakes cases, use a second pass that asks a model to find unsupported statements in the answer.
CHECK = """List every statement in ANSWER that is NOT supported by SOURCES.
Return JSON: {"unsupported": ["..."]}. Return an empty list if all are supported."""

def unsupported_claims(gateway, answer, sources):
    msg = [{"role": "system", "content": CHECK},
           {"role": "user", "content": f"SOURCES:\n{sources}\n\nANSWER:\n{answer}"}]
    return json.loads(gateway.complete("verifier", "large", msg, temperature=0).text)["unsupported"]
4. Allow abstention
Reward the system for saying it does not know. Evaluate abstention separately, and route abstentions to a person or to a search result list.
5. Lower the temperature, with limits
Low temperature reduces variety and some errors, but it does not make claims true. Use it for factual tasks, and rely on the other layers for correctness.
Measure it
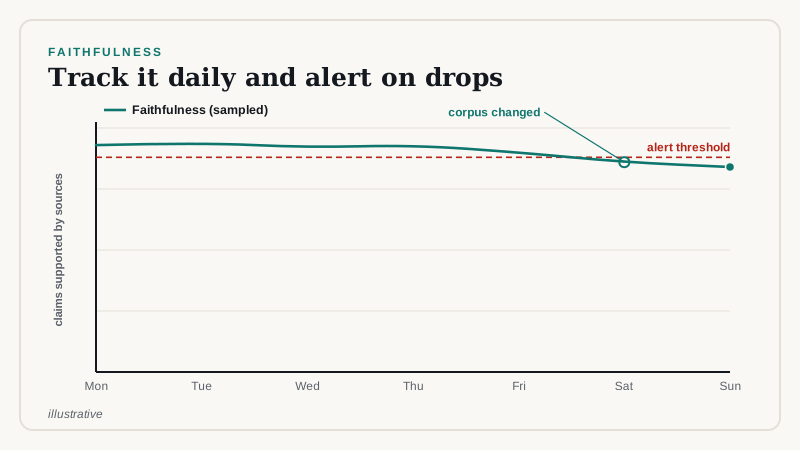
- Faithfulness: the share of claims supported by sources.
- Answer rate versus abstention rate on unanswerable questions.
- Citation validity.
- Human audit of a random sample each week.
Types of hallucination
- Fabricated facts: names, numbers, or events with no source.
- Fabricated citations: references that look real and are not.
- Misreading of provided context: the source is there, and the model draws the wrong conclusion.
- Overgeneralization: a true statement stretched beyond what the source supports.
Each type needs a different check. Citation checks catch the second, quote matching catches parts of the first and third, and a claim-by-claim verifier catches the fourth.
Measuring faithfulness
def faithfulness(claims, supported_flags):
    """Share of claims judged supported by the sources (flags come from a verifier or human review)."""
    return sum(supported_flags) / len(claims) if claims else 1.0

def report(results):
    return {
        "faithfulness": mean(r["faithfulness"] for r in results),
        "unsupported_examples": [r["id"] for r in results if r["faithfulness"] < 1.0][:10],
    }
Prompt patterns that help
- Put the sources first and the question last, and refer to sources by number.
- Say explicitly what to do when the sources are insufficient.
- Ask for short answers; length gives more room for drift.
- Ask the model to quote the supporting sentence before answering, then verify the quote in code.
When to use a second pass
A verification pass adds cost and latency, so reserve it for answers where an error matters. A tiered design works well: run code checks on everything, add the model verifier for high-impact categories, and send anything still uncertain to a person.
Monitoring in production
Sample answers daily, run the faithfulness check, and chart it. Alert when it falls. Add every confirmed hallucination to the evaluation set, so the same failure cannot return unnoticed.
Communicating limits to users
Tell users that answers come from specific documents, show the sources, and make it easy to open them. People calibrate their trust when they can check. Avoid claiming that the system is always correct; promise a process for catching and fixing errors instead.
How we can help
We audit existing GenAI systems for hallucination risk with your real queries, then implement grounding, verification, and monitoring. Request an audit.
Related reading
Need help implementing this?
Our consultants run architecture reviews and build production pilots. Book a free scoping call to talk through your design.
Book a Free Scoping Callor email us at hello@deepvero.com